hihi! i’m maggie hays

tl;dr: fifteen years in data, lately building it for humans and agents alike. Scroll for the principles I build by, stuff I’ve talked about and built, where I’ve worked, and (most importantly) my dogs.

Things I love to do

And when each one was part of the job

BraintreeTech Lead / Product Manager, Data TeamSpotHeroSenior Product Manager, Data ServicesDataHubFounding Product Manager + Data Person
Product management
Product analytics
Reporting & BI
Analytics engineering
Data quality & contracts
Agents & evals
Tech lead
Public speaking
  1. Reporting & BI10.8 yrs
  2. Product management8.8 yrs
  3. Product analytics8.3 yrs
  4. Data quality & contracts7.4 yrs
  5. Analytics engineering7.3 yrs
  6. Tech lead6.3 yrs
  7. Public speaking5.1 yrs + 3 earlier talks
  8. Agents & evals0.8 yrs

patterns & principles

The practices baked into how I work every day, the stuff I keep coming back to. Each comes with a little chart of how I think about it, plus a few hills I’ll gladly die on.

Data modeling

The patterns I build every model on.

hills i'll die on

  • Borrow from the classic modeling playbooks, but only what's actually useful to you.
  • Refactor early and often, and update your standards as you go.
  • Name things what they are: etl_updated_at, not just updated_at.
  • DRY above all: define business logic once, reuse it everywhere.
  • Leading commas beat trailing commas. Forever.
  • No one- or two-letter aliases. Spelling out a whole word isn't that hard.

The stack I keep building

Data modeling is only one piece of the data stack puzzle.

HubSpotSlackGongLinearGitHubMixpanelS3FivetranPythonrawaudit logsstagingintermediateanalyticsHexClaudeCustom AgentsCustomer.ioHubSpot

Quality & orchestration

Catch it early, alert on what matters.

hills i'll die on

  • Put data quality checks as early in the dependency chain as you can.
  • Freshness and uniqueness are table stakes for every dataset.
  • Distribution and shape checks earn their keep on core metrics. Everywhere else they're noise.
  • Keep DAGs trim. One mega-DAG is a ticking time bomb of late data and tangled dependencies.

Nightly pipeline run

Freshness and uniqueness checks up front, so bad data stops before it ships

extract_mixpanelextract_hubspottest_source_freshnessload_stagingtest_stagingload_intermediatetest_intermediateload_analyticstest_analytics

Product analytics

Good product data is a team sport.

hills i'll die on

  • Partnering directly with engineering is non-negotiable: whoever ships the click-stream events should know how they get used.
  • Don't micromanage every event. Chase the inconsistencies that actually hurt the business or the data.
  • Adoption, conversion, retention and funnels need a tight loop with the PM: the exact right events, and what shifted between releases.
  • It's an ongoing partnership, not a request queue.

Activation funnel

Every step is an event someone shipped. Build it with eng, not for them.

Data for agents

Honestly, I'm still building my playbook here.

hills i'll die on hills i'll probably die on, eventually

  • Context engineering and evals are brand new. Do what works for your team now and restructure fast.
  • It's not as easy as pointing agents at a folder of markdown, but don't stack context on context on context either.
  • Write evals for the questions you've answered a million times that still confuse people, and that matter to the business or sit at the center of your lineage.
  • Decide up front what kind of context goes where, keep it flexible, and revisit often.

Agent evals

Write evals for the questions you've answered a million times

prompt

“What is the daily and monthly active user count by account?”

pass rate
79% 11 of 14 runs
last 5 runs
latest run
fail Oct 9
checks
2/3 passing

Needs attention · contradicting context

Two certified DAU definitions: fct_usage counts any event, the Hex semantic model counts sessions.

suggested fix Pick one DAU definition, deprecate the other, and say which one the agent should use in its context docs.

grading criteria

passMust reference metric · DAU and metric · MAU
agent did
Referenced both certified metrics
MCP servers
DataHub
context used
metric documentation
passUse event_date to bound a 30-day window
agent did
Filtered event_date >= current_date - 30
MCP servers
dbt, Snowflake
context used
query history
failCount active users the way the semantic model does (sessions)caused by the warning
agent did
Counted any event as active
MCP servers
DataHub, Snowflake
context used
metric documentation, glossary terms

Data storytelling

Pretty isn't the same as useful.

hills i'll die on

  • Never use a pie chart. Donuts too.
  • Learn which chart fits which kind of analysis.
  • When you present, explain what it means, not what it looks like. People have eyes; they need the interpretation.

Co-purchases

Pretty, sure. My read: apparel drives the cart, and home is practically its own store

ApparelShoesAccessoriesBeautyHome

Top pairs · orders with both

  1. Apparel+Shoes420
  2. Apparel+Accessories380
  3. Apparel+Beauty210
  4. Shoes+Accessories190
  5. Accessories+Beauty160
  6. Beauty+Home120
  7. Apparel+Home90
  8. Shoes+Beauty70
  9. Accessories+Home55
  10. Shoes+Home30

Knowledge graphs & metadata

Yes, metadata is all the rage right now. It's all the rage for a reason: agents won't get this stuff right without it.

hills i'll die on

  • Whatever your team size or stage, start a metadata strategy: where data came from, who owns it, what it represents.
  • Whatever the tool, set those standards early and build tooling and CI around them.
  • Knowledge graphs are underrated. Understanding how concepts relate is the difference between a metric and an insight.

Knowledge graph

The winding web of apps and workflows behind every business concept

CustomerOrderPaymentRefundProductReviewHubSpotShopifyStripeZendeskYotpoApp StoreCheckout flowReturns flowReview request

15 entities · 18 relationships

  1. Customer places Order
  2. Order contains Product
  3. Payment settles Order
  4. Refund reverses Payment
  5. Review rates Product
  6. HubSpot enriches Customer
  7. Shopify registers Customer
  8. Shopify creates Order
  9. Shopify lists Product
  10. Stripe captures Payment
  11. Stripe issues Refund
  12. Zendesk approves Refund
  13. Zendesk collects Review
  14. Yotpo collects Review
  15. App Store hosts Review
  16. Checkout flow triggers Payment
  17. Returns flow triggers Refund
  18. Review request asks for Review

stuff i’ve talked about

Me, talking shop out loud: leadership and strategy for data practitioners and team leads, in talks, panels, DataHub Town Hall feature demos and the occasional article.

Open on the original site ↗

stuff i’ve built

A couple of things I've built in the open, plus what my GitHub's been up to lately.

GitHub activity

Commits by month, public and private repos

051015NovJan ’26MarMayJulSep
Code by language · lines changed in merged PRs, last 12 months
  • Python 43%+3,053−0
  • Markdown 29%+1,990−93
  • JSON 12%+827−0
  • YAML 11%+706−57
  • Other 5%+375−14

fifteen years of data

Price-sensitivity models predicting how ~5M customers react when rates move, analytics engineering for org-wide self-serve reporting, leveling up pipeline rigor so data ships like a product, and leading product strategy and delivery for SaaS features that power everyday data workflows at 3k+ organizations. The through-line: data stuff shouldn’t be this complicated, so I’m always hunting for ways to make it delightful.

  1. 8th hire at seed stage, first PM and first data person. I've owned a lot of the roadmap over the years: open source, the ingestion framework + source connectors, context generation to bootstrap context layers, and eval definition + execution with AI-suggested fixes. Still building the data side too: warehouse, telemetry and analytics agents.

    1. 2026Analytics agents: PM for in-app context generation, plus our internal context curation strategy
    2. 2024Grew the data team: hired our first Sr. Analytics Engineer
    3. 2023Stood up the warehouse: 15 sources → Snowflake → dbt
    4. 20218th hire at seed stage, first PM and first data person; picked up product event tracking
    Highlights (6)
    • Warehouse (2023): 15 Fivetran sources → Snowflake → dbt, with CRM + community data for top of funnel.
    • Hired our first Sr. AE; together we set modeling standards and made S3 JSON backups schema-proof Snowflake tables.
    • Mixpanel telemetry since 2021: 100–130 event types, naming standards, malformed-event alerts.
    • Analytics agents: the Hex agent is used by 40% of the company, 88% pass rate across 37 evals.
    • Customer health agent for CSMs: prompt cut 65%, rubric 81% → 87%.
    • Metrics + semantic models, discovery to rollout; proposed the Metric entity (DataHub Cloud 2.1).
  2. Owned the data platform (Redshift, S3, Athena, Looker, DataHub) and the roadmap for data engineering, data science and analytics.

    1. Q1 2021ETL retooling + migration
    2. Q4 2020Partnered on the operator-facing dashboard
    3. Q4 2019Partnered with customer-facing eng teams on event telemetry contracts, consistent across platforms
    Highlights (5)
    • Data contracts on 80% of click-stream events: 95% fewer data quality issues.
    • Reworked 200+ ETL jobs: 44% fewer broken pipelines.
    • DataHub for discovery across 10k+ assets: 30% fewer ad-hoc requests.
    • First dynamic pricing model + its operator dashboard (39% of partners within 6 months).
    • One set of KPIs across Finance, Supply and Support.
  3. Ran the roadmap for 9 analytics engineers, covering internal and customer data needs with Product, Account Management, Sales, Ops, Underwriting and Support. Kept everything we shipped high-quality and reliable. Stack: Redshift, S3, Airflow, Looker.

    1. H1 2019Full refactor + migration of the core data model
    2. 2018Productized merchant-facing data exports, delivered daily to Uber, Airbnb and more
    3. 2017Promoted to manager of the 9-person data team
    4. 2016Promoted to tech lead, focused on data model design
    Highlights (3)
    • 75+ daily data exports for clients like Uber, Airbnb, Wish and Stitch Fix.
    • Core data model for 15 business areas and 200+ stakeholders.
    • Self-serve data resources: 26% fewer ad-hoc requests.
  4. Where it started: figuring out how sensitive deposit customers are to rates, and helping execs see what a rate change would actually do.

    1. early 2015Built and shipped those models as a self-serve tool to simulate rate changes on savings products
    2. mid 2014Showed execs where we were losing share of wallet as rates shifted
    3. mid 2013Delivered state-level interest rate recommendations that set pricing strategy for the next 6 months
    Highlights (5)
    • Price elasticity models: customer-level (~5M customers, 5 yrs) and state-level (4 states, 3 yrs).
    • Launch analysis: Flow of Funds behavior for 35M customers, plus competitor inflows and outflows by region.
    • An Excel pricing tool on model output for 690 segments, built for an exec partner.
    • Directed 4 developers on database design; the database go-to for 200+ analysts.
    • Tools: SAS, SQL, UNIX, Excel, PowerPoint, MicroStrategy.

let’s talk shop

Always happy to nerd out about data, agents or your messiest pipeline. Say hi!
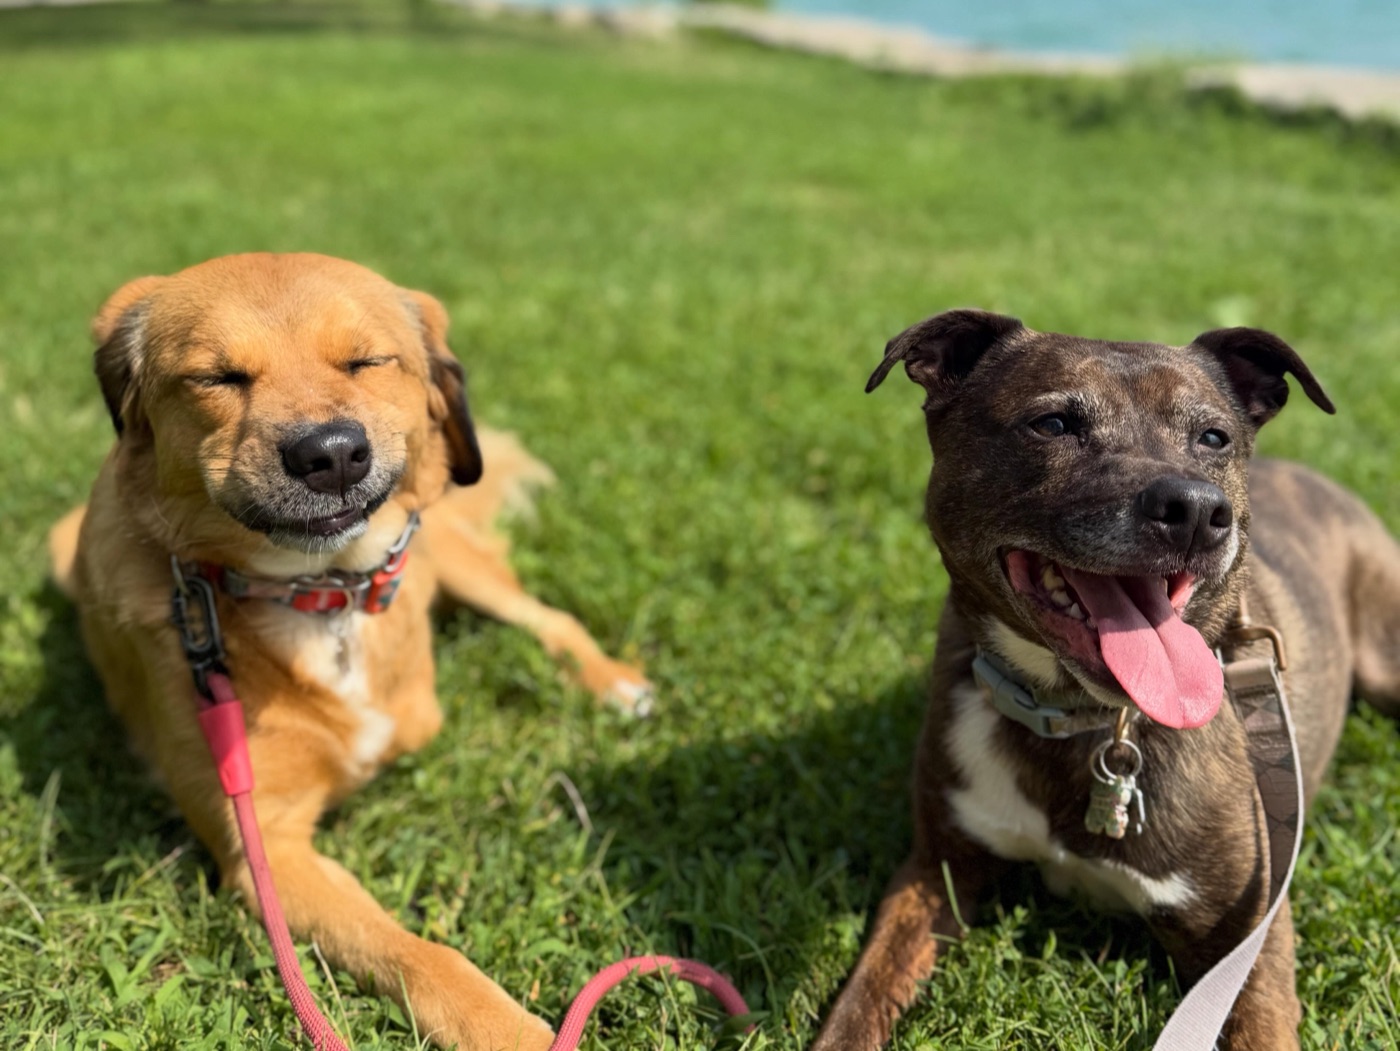
fyi these are my dogs

Nellie and Marlowe lying in the grass, one squinting happily, one with her tongue out
Nellie and Marlowe are perfect and I love them :)